On 15 September 2026 Cloudflare changed what its Block setting covers. The control that used to keep AI companies away from your pages now turns away Google, Bing and Apple as well.
Nobody was dropped from search when that happened. The danger is the next time somebody opens those settings, sees a button called Block, and presses it for the reason it has always been pressed.
First, the good news. Nothing broke
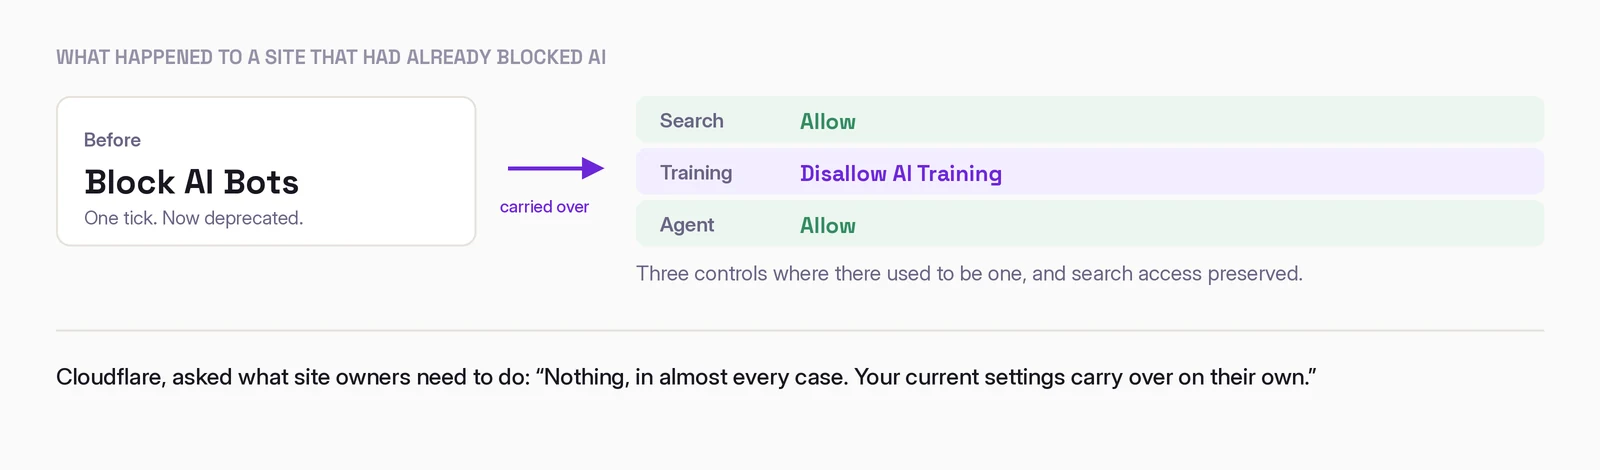
If you had already told Cloudflare to keep AI crawlers off your site, you did not lose anything on 15 September. Cloudflare answers the question directly in its announcement, under the heading of what site owners need to do:
“Nothing, in almost every case. Your current settings carry over on their own.”
A legacy Block AI Bots tick became a setting called Disallow AI Training, with Search left on Allow. Previous granular Training choices of Block, or Block on pages with ads, were migrated the same way. Your pages stayed in Google, and in almost every case you did not have to touch anything.
That is worth saying plainly, because the alarming version of this story is the one that travels. Nobody quietly vanished from search results.
The risk is the next click, not the last one
Here is the sentence that changed. Cloudflare describes the Block setting and the one called Block on pages with ads, and says both:
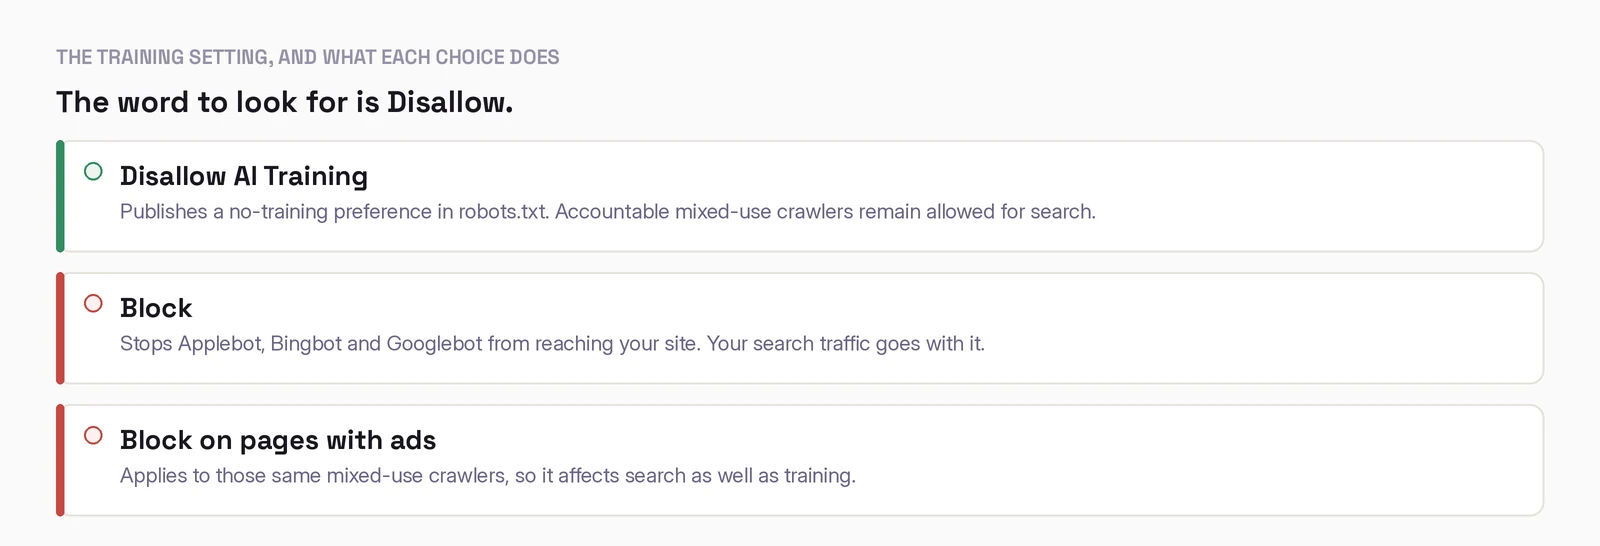
“now apply to mixed-use crawlers, including Applebot, Bingbot, and Googlebot, so either setting impacts search as well as training.”
Cloudflare is not hiding this. It is the stated intent:
“If you want mixed-use crawlers gone entirely, you now have to say so. Select Block. It will stop Applebot, Bingbot, and Googlebot from reaching your site”
So picture the ordinary version of this. Somebody on your team decides this month to keep AI models off the company site. They open Cloudflare, they see a setting called Block, and they press it. That is your search traffic, switched off by a person doing the right thing with the wrong button.
One bot does two jobs, which is the whole problem
Cloudflare's word for the thing at the center of this is a mixed-use crawler, which it defines as:
“a single crawler doing both Search and Training”
Google, Bing and Apple each run one. The same visit that puts you in search results also collects the text that trains a model. Turn that crawler away and both jobs stop, the training you wanted gone and the search you wanted kept.
That is why one button could not serve both purposes any more, and why Cloudflare split the controls apart rather than leaving a switch that quietly meant two things.
Which setting actually does what you want
There are now three controls, Search, Training and Agent, and the Training one is where this decision lives. The setting to look for has the word Disallow in it:
“Disallow AI Training: Bot Preference Sync publishes the applicable no-training preference in robots.txt. Accountable mixed-use crawlers remain allowed for search.”
Disallow AI Training publishes your preference and keeps you findable. Block turns away the same visitors that bring you readers. Two settings, two words apart, and one of them costs you a channel.
Two numbers explain why the buttons were split
Cloudflare published the shape of what its customers actually choose. Less than 1% of Cloudflare sites choose to block search bots. By contrast, 17% of sites choose to enable some mechanism to block training.
Almost everybody wants the same arrangement. Stay findable, stop the training. The old single control forced those two wishes through one switch, and the new split is Cloudflare's answer to that.
The promise, and the piece that is not built yet
For a crawler to keep search access after you opt out of training, Cloudflare requires it to meet a bar it calls Accountable. Apple, Google, and Microsoft all demonstrate that they meet the qualifications to be Accountable. One of the four requirements is the one that matters to a publisher:
“Assurance that opting out of AI training will not affect traditional search results.”
Now the caveat, and it is a real one. Bing does not honor the no-training preference yet. Cloudflare says Microsoft is:
“currently building the mechanism to also respect a 'no training' preference in robots.txt at the domain/site level, targeted for early 2027.”
So the preference is published, and Bing is not reading it yet. That is a target, not a delivery date, and it is the honest limit on all of this.
There is a second thing not here yet. On how much of your content appears inside AI summaries, Cloudflare says only that “By early next year, our goal is to let you control how much of your content is included”. A goal, not a control you can use today.
If your site earns money from advertising, check one more setting
Cloudflare also changed the defaults for domains onboarded from 15 September. Sites that earn from advertising start on the more restrictive preset: Training set to Disallow AI Training, and Agent set to Block on pages with ads.
The reasoning is stated plainly, and it is the clearest argument in the whole announcement:
“Ad revenue depends on a human actually seeing the page. Training replaces that visit with an answer; agents fetch the page with nobody there to see the ads.”
If your business model is impressions, that is the sentence to take to whoever owns the site.
What to do this afternoon
Ask whoever holds your Cloudflare login one question. Does our Training setting say Disallow AI Training? If it says anything with Block in it, you are telling Google to leave.
Write the answer down somewhere the next person will find it. The failure here is not technical. It is a reasonable person pressing a reasonably named button a year from now.
If you sell advertising, read the Agent setting too. It is separate from Training, and for an ad-supported site it is the one that protects the impression.
Do not act on the alarming version of this story. Your existing settings were carried over. The thing to prevent is ahead of you, not behind you.
One setting decides whether Google can reach your pages. It takes ten minutes to read it, and nobody sends a warning when the crawlers stop coming.
Verified 18 September 2026 against Cloudflare's blog post of 15 September 2026, "Have it both ways: stay discoverable in search while disallowing AI training" by Bryan Becker. Quotations are reproduced exactly. Cloudflare's migration preserved existing search access; no site lost search traffic as a result of the change itself.
Working out where AI actually fits in your marketing?
I write these while building the systems behind them: measurement, creative pipelines, and agents that do real work. Connect on LinkedIn and tell me what you are working on. That is where these conversations start.
Connect on LinkedIn